Problem
Finding a similar movie should be quick, with recommendations that do not require an account or another paid API request.
Constraints
The deployed site must work without a TMDb secret. Recommendations should be reproducible and fast to serve.
Approach
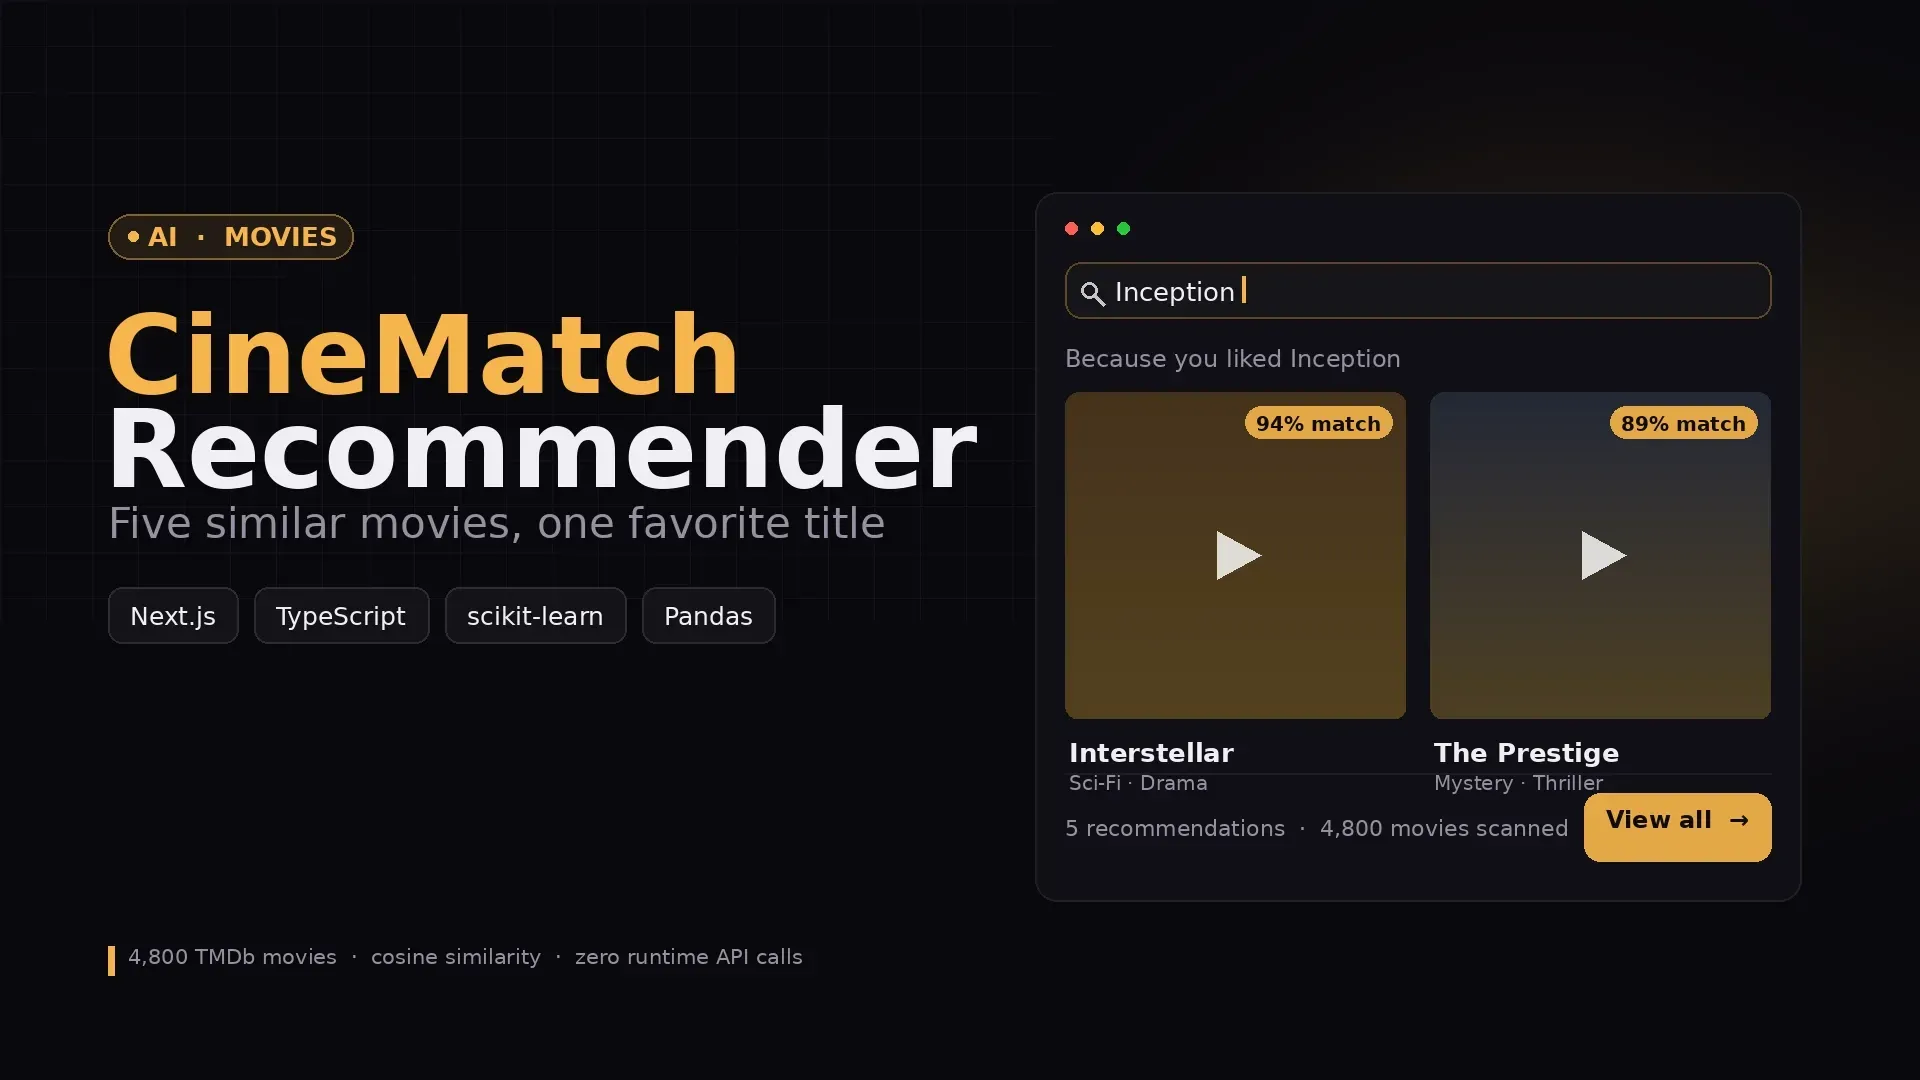
Plot, genre, cast and crew metadata are combined into features. CountVectorizer produces bag-of-words vectors, and cosine similarity selects five nearby titles.
Architecture
TMDb metadata → offline Python feature pipeline → cosine-similarity ranking → precomputed JSON → static Next.js interface.
Challenges and trade-offs
Precomputing removes runtime provider dependencies and key exposure. The trade-off is a fixed catalogue that requires an offline rebuild for new movies. This is distinct from the TF-IDF recommender built during the DRDO internship.
Results
Roughly 4,800 movies are searchable with five recommendations per title. Python and TypeScript checks cover both sides of the pipeline.
What I would do next
Compare recommendation quality against alternative feature representations and add a reproducible catalogue refresh process.